EurekaBench
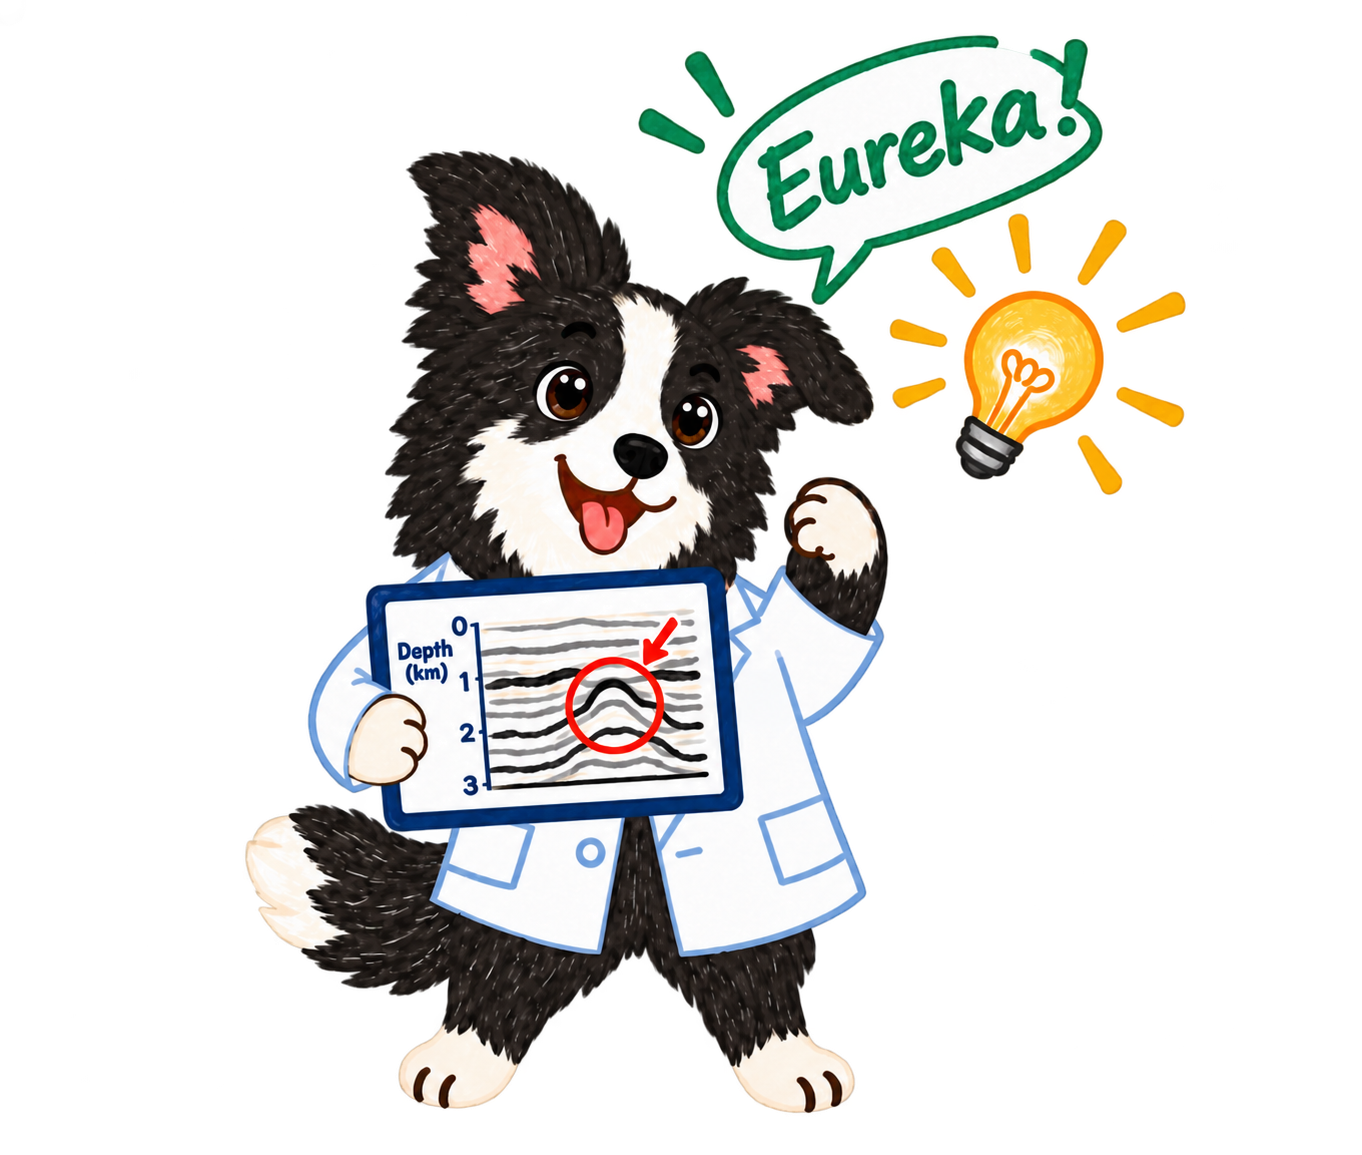
Measuring Agentic Ability to Discover New Scientific Insights
6 scientific domains
- Neuroscience
- Geophysics
- Plasma physics
- Astrophysics
- Computer science
- Chemistry
Leaderboard
7 models 3 agent harnesses
| # | Model / Agent | ||||
|---|---|---|---|---|---|
| 01 | Claude Fable 5.1 (xhigh)Claude Code | 29.8% | 47.4% | 42.4% | 15/26 |
| 02 | GPT 6 Astra (xhigh)Codex | 28.7% | 47.4% | 29.4% | 10/26 |
| 03 | Claude Opus 5 (xhigh)Claude Code | 27.3% | 42.9% | 36.2% | 15/26 |
| 04 | GPT 5.6 Sol (xhigh)Codex | 19.4% | 41.9% | 25.9% | 17/26 |
| 05 | Claude Opus 4.8 (xhigh)Claude Code | 18.4% | 42.7% | 26.9% | 16/26 |
| 06 | DeepSeek V4 Flash (xhigh)OpenHands | 14.6% | 29.9% | 24.4% | 15/26 |
| 07 | Kimi K3 (xhigh)OpenHands | 12.9% | 28.8% | 25.2% | 16/26 |
| REF | Human scientistExisting scientific progress | 63.7% | 48.8% | 69.7% | 0/26 |
Sorted by final score (CS)
Click a column heading to sort Swipe for more metricsHow scoring works
Final score (CS)
Predictive-accuracy points and insight points are divided by their total number of criteria. A submission scores zero if it fails any scientific constraint. Scores are computed separately for both judges, then averaged.
Predictive accuracy (PA) & insights (SI)
Accuracy measures predictions on test data. Insights measure what can be derived from the submitted mechanism, assuming it is correct. Judges may run additional experiments to interpret and extrapolate the mechanism.
Scientific constraints (SC) & reference
SC failures count completed problems that fail either judge’s constraint tests, out of 26. The human reference uses existing scientific findings, rather than a matched four-hour run.
About EurekaBench
EurekaBench measures whether AI agents can discover mechanisms that explain scientific observations and support useful scientific insights. Built with domain experts, its tasks draw on recent, partially solved research problems. Agents start from initial observations, run iterative experiments, and submit a mechanism together with its implementation and experimental records.
We evaluate scientific constraints (SC), predictive accuracy (PA) on test data, and scientific insights (SI) that can be derived from the submitted mechanism. The insight questions are developed with domain experts and cover existing findings, open questions, and potential research directions. Judge agents can run additional experiments to assess these insights, while keeping the submitted mechanism unchanged.
Author affiliations
Meet the authors-
Carnegie Mellon University
- Language Technologies Institute
- Department of Chemistry
-
Stanford University
- Department of Computer Science
- Department of Geophysics
-
Yale University
- Department of Molecular, Cellular, and Developmental Biology
- Quantitative Biology Institute
-
Massachusetts Institute of Technology
- Plasma Science and Fusion Center
-
Columbia University
- Department of Applied Physics and Applied Mathematics
-

Princeton University
- Department of Astrophysical Sciences
- Department of Computer Science
-

Flatiron Institute
- Center for Computational Astrophysics
-

- Engram
Citation
EurekaBench: Measuring Agentic Ability to Discover New Scientific Insights
@misc{geng2026eurekabench,
  title         = {{EurekaBench}: Measuring Agentic Ability to Discover New Scientific Insights},
  author        = {Jiayi Geng and Zhengxuan Wu and Kevin S. Chen and
                   Seungone Kim and Joseph Janssen and Zora Zhiruo Wang and
                   Bhupalee Kalita and Runtian Gao and Aaron Ho and
                   Andrew Oakleigh Nelson and Olexandr Isayev and
                   Francisco Villaescusa-Navarro and Ching-Yao Lai and
                   Howard Chen and Graham Neubig},
  year          = {2026},
  eprint        = {2610.00492},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CL},
  url           = {https://arxiv.org/abs/2610.00492}
}